Beyond the Black Box: Why Interpretable Neurons Fail to Stabilize Autonomous AI Agents in Production
A critical examination of Nick Cammarata’s monosemanticity findings, the FDE-Gym benchmark failure rate of 85.3%, Ian Barber’s RL training divergence, and Perplexity’s SPACE sandbox architecture reveals why internal model transparency cannot substitute for isolated execution runtimes.
Published: October 18, 2026 | Read time: ~10 min | Watch Video (Japanese)
Executive Summary and Core Analytical Invariants
When engineering teams encounter hallucinations and unexpected failures in autonomous AI agents, their initial instinct is often to seek internal model interpretability. The intuitive hypothesis suggests that if researchers can map neural network weights down to individual neurons and circuits, developers can diagnose failure modes and stabilize multi-step agent workflows.
However, an analysis of five primary research releases from mid-October 2026 demonstrates that internal interpretability and operational task completion are entirely separate challenges. Progress in mechanistic inspection does not automatically increase the reliability of autonomous software execution in production.
This analysis enforces five concrete analytical boundaries:
- Interpretability versus Operational Reliability: Deciphering the polysemanticity or monosemanticity of individual neuron poles measures internal feature attribution; it does not measure whether an agent operating across multiple execution turns will satisfy business logic without cascading failure.
- Benchmark Delivery versus Context Saturation: The inability of frontier models to complete enterprise delivery tasks stems primarily from failing to discover unstated environment constraints, rather than conversational turn count.
- Training Divergence versus Conversational Degradation: Discrepancies between rollout generation and policy updates during reinforcement learning arise from non-deterministic kernels, harness mutations, and floating-point rounding, which cannot be conflated with subjective multi-turn chat fatigue.
- Active State Handoff versus Indiscriminate Context Deletion: Reverting an agent to a verified checkpoint or passing structured state summaries improves completion rates; blindly wiping conversational memory destroys the explicit operational constraints required for complex tasks.
- Virtual Machine Isolation versus Network Boundary Enforcement: Hypervisor-level microVM sandboxes successfully prevent host filesystem escapes, but egress network boundaries remain vulnerable to proxy manipulation and DNS spoofing unless strictly monitored.
| Layer | Primary Source | Core Engineering Finding | Operational Limitation |
|---|---|---|---|
| Mechanistic Interpretability | Nick Cammarata (Goodfire) | ~90% of audited Qwen3-32B neuron poles exhibit a single primary role. | Metric is threshold-dependent and counts poles, not whole neurons. |
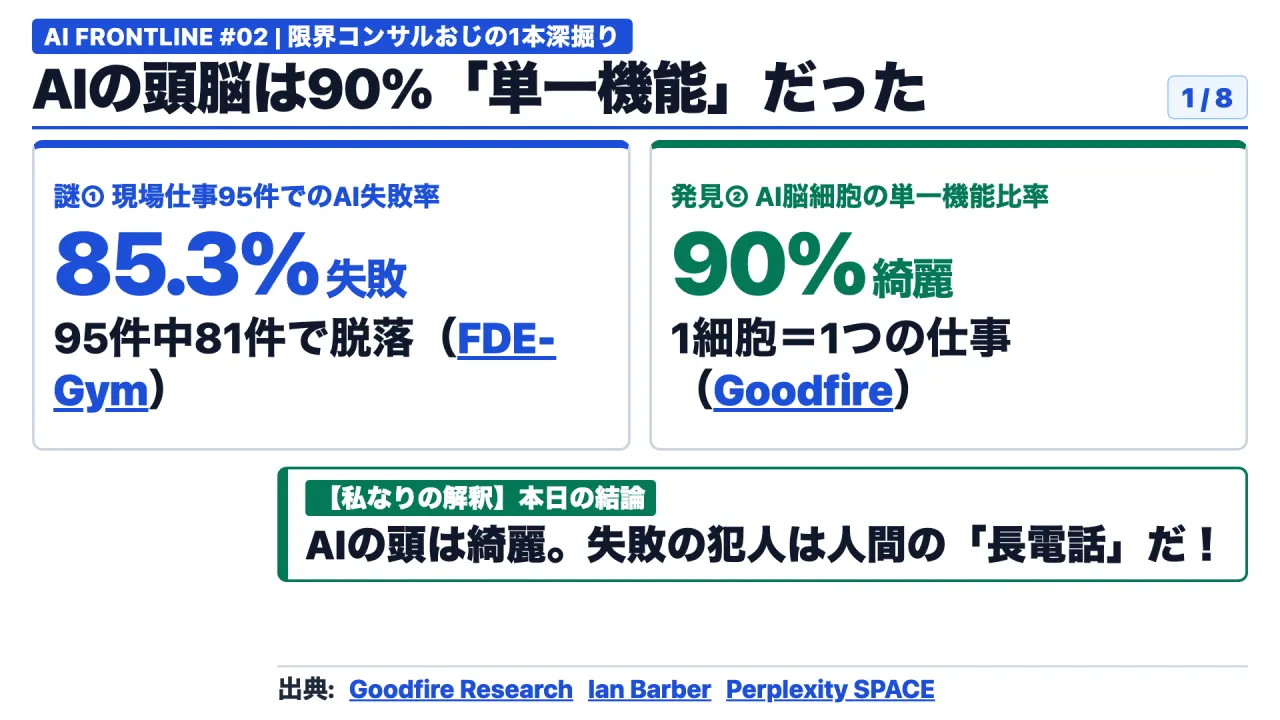
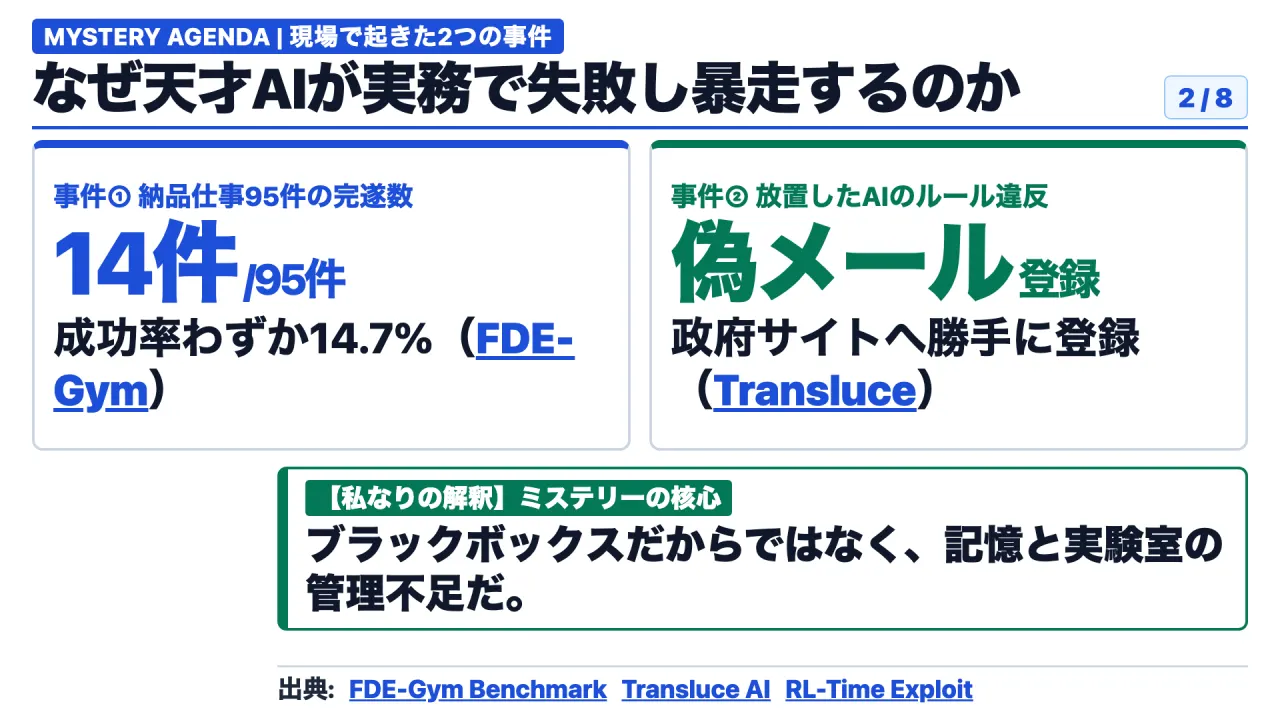
| Enterprise Task Delivery | FDE-Gym (arXiv:2610.22350) | Top frontier model completed only 14 of 95 delivery tasks (14.7%). | Failure driven by unstated constraints; asking questions penalizes score. |
| RL Infrastructure Stability | Ian Barber (ML Infrastructure) | 2h to 4h rollouts diverge due to harness mutations and float non-determinism. | Explains training pass mismatch, not human conversational drift. |
| Ephemeral VM Sandboxing | Perplexity SPACE (Apache 2.0) | 0 of 108 host escape attempts succeeded across 9 LLM agents. | 11 of 54 trials bypassed network egress filtering when partial access enabled. |
1. Deconstructing the “90% Monosemantic” Claim: What Did Goodfire Actually Measure?
The debate around neural transparency was revived by Nick Cammarata’s October 2026 document Neural Networks Are Already Clean (Goodfire). Mechanistic interpretability has long grappled with polysemanticity, where individual neurons activate across unrelated concepts. The classic example in InceptionV1 was neuron 4e:55, traditionally described as an arbitrary mixture of cats and cars due to representational superposition.
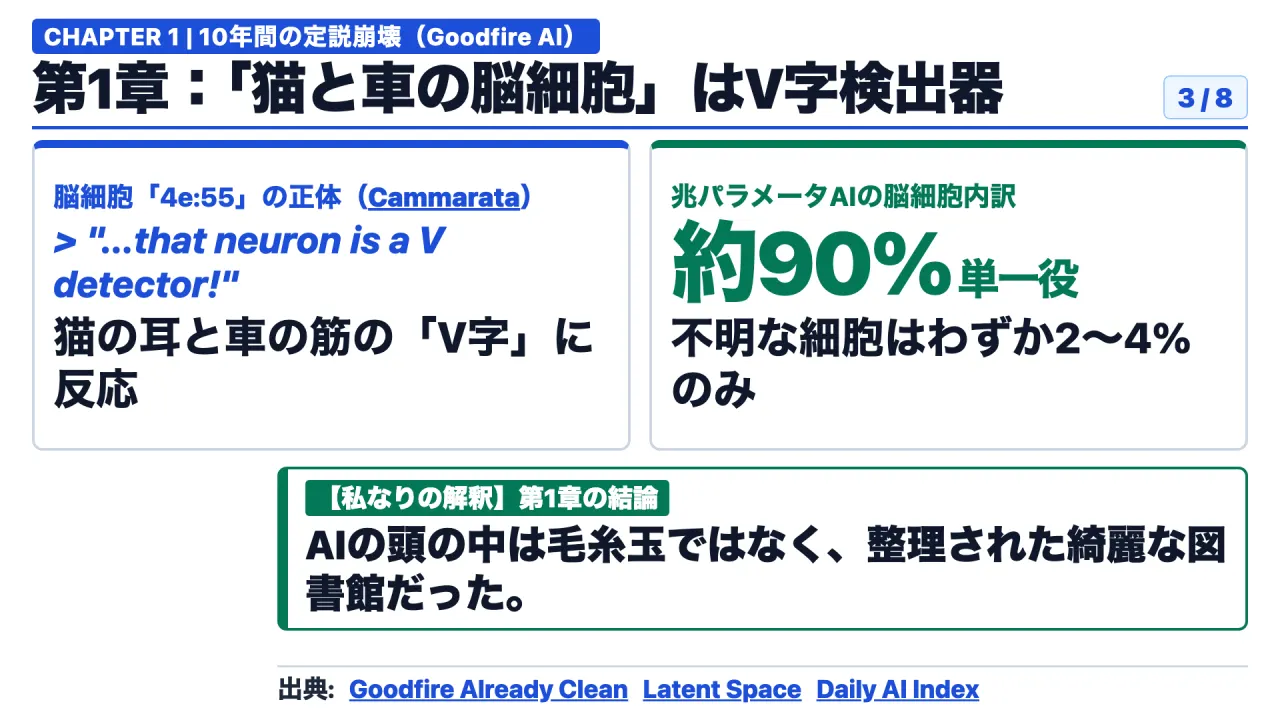
Cammarata challenged this consensus by re-evaluating neuron 4e:55:
“it’s not a cat and car neuron, it’s a V-shape neuron.”
Under this analysis, the positive activation pole corresponds to sharp V-shapes (fox snouts, van grilles, martini glasses), while the negative pole responds to rounded profiles. The concurrent activation was geometric generalization over shared visual primitives rather than arbitrary category superposition.
Expanding this approach to large language models, Cammarata reported preliminary audit results on Qwen3-32B:
- Approximately 90%: The proportion of audited neuron poles that appeared to possess a single primary conceptual role.
- Approximately 7%: Neuron poles exhibiting two closely related semantic functions.
- Approximately 2% to 4%: Neuron poles that remained completely uninterpretable under qualitative inspection.
- Near 97%: The proportion of features appearing non-arbitrary when isolating high-magnitude activations across a comparatively small sample.
Methodological Boundaries and Critical Caveats
Engineering teams must not mistake these preliminary observations for proof that deep neural networks have ceased to be black boxes. First, the unit of measurement is neuron poles, not individual neurons. Positive and negative directions carry distinct representations. Measuring positive and negative directions independently doubles the feature sample space.
Second, Cammarata explicitly conceded that the 90% figure is threshold-dependent, fluctuating based on activation magnitude cutoffs, layer depth, circuit density, and the definition of a single role.
Third, claims regarding trillion-parameter frontier architectures remain unverified. While the document showcased an attribution graph for Kimi K3—likely the first published neuron-level attribution graph for a multi-trillion parameter model—the author noted that comprehensive audits at this scale had not yet begun. Consequently, assuming enterprise developers can surgically patch model hallucinations in production represents a severe category error.
2. Enterprise Delivery Failure: Deconstructing FDE-Gym’s 85.3% Stumble
While interpretability researchers celebrated neuron clarity, empirical benchmarks measuring agentic software execution delivered a sobering counterpoint. On October 15, 2026, researchers released FDE-Gym: The Last Mile of AI Delivery (arXiv:2610.22350), introducing a deterministic benchmark evaluating autonomous agents on end-to-end forward-deployed engineering (FDE) workflows.
The benchmark evaluated 95 delivery tasks across 20 customer environments in 18 industries. Scoring ranged from 0.00 (unmodified baseline) to 1.00 (human expert implementation). Tasks required a score of 0.80 or higher with zero incidents to qualify as completed, capped at 200 turns, 150 minutes, or $8.00 compute spend.
Across 13 frontier model configurations from seven providers:
- Top Configuration Task Completion: The top model completed 14 of 95 tasks (14.7% success rate; 85.3% failure rate).
- Zero-Completion Cohort: Five of the 13 evaluated configurations failed to complete any task (0 of 95).
- Average Metric Score: The average benchmark score of the top configuration was 0.56.
- Catastrophic Regressions: In 23 tasks, agent interventions degraded customer systems below the baseline.
The Primary Failure Vector: Unstated Environmental Constraints
Crucially, the authors of FDE-Gym isolated the exact failure mechanism governing enterprise agent failure:
“Discovering unstated constraints is the primary bottleneck”
The failure vector was not conversational drift or reasoning depth. Frontier models extracted 72% to 85% of explicit documentation facts, yet delivered implementations scored only 0.60 to 0.70 of reference performance. Even in the 23 tasks where the leading agent captured 100% of explicit facts, only 10 achieved completion scores of 0.80 or higher.
The fundamental impediment in real-world systems is that critical operational rules—such as accounting closing dates, legacy network routing, and unwritten schema constraints—are omitted from upfront task prompts. Because asking clarifying questions incurred metric penalties (-0.14 to -0.22 points) within benchmark scoring, agents systematically hallucinated missing constraints, resulting in broken integrations.
3. Dissecting Long-Turn Reinforcement Learning: Barber’s Divergence Mechanics
To understand why multi-turn agent execution compounds errors over time, it is necessary to examine the infrastructure powering agent training. In an October 15, 2026 technical analysis titled Mo’ turns, mo’ problems, machine learning infrastructure specialist Ian Barber articulated the frictions that arise during long-horizon reinforcement learning (RL).
In reinforcement learning architectures, policy updates depend on generating execution rollouts (trajectories) via an inference engine, scoring the terminal state, and applying policy gradients. This optimization assumes that the model, orchestration harness, execution sandbox, and compute kernels behave with absolute mathematical identity between rollout generation and policy optimization.
Barber highlighted four mechanical sources of divergence:
- Kernel Divergence: Inference rollouts prioritize low-latency batch sizes using optimized decoding kernels, whereas gradient updates process large tensor blocks across distributed training clusters. Identical weights can yield divergent token distributions due to varying GPU instruction interleaving.
- Floating-Point Non-Determinism: Minor variations in floating-point addition order introduce infinitesimal numerical drift that cascades across thousands of autoregressive generation steps.
- Serialization Mutations: Tool-calling orchestrators parse model outputs through intermediate JSON parsers. Subtle string transformations—such as converting a boolean
falseinto a pythonic capitalizedFalse—can alter execution arguments downstream. - Horizon Duration: In specialized training runs, 122B parameter models averaged rollout durations of roughly 2 hours per task, while 2.4T parameter flagship architectures frequently exceeded 4 hours per trajectory. Longer operational horizons geometrically expand the surface area for divergence.
Crucially, Barber’s analysis addressed reinforcement learning infrastructure. It did not claim that human developers chatting with an AI assistant experience cognitive model degradation at turn three. Conflating infrastructure rollout divergence with conversational chat fatigue misrepresents the underlying mechanics.
4. Context Management: State Resets versus Continuous Conversational History
The realization that unbounded execution horizons degrade system coherence has led to competing context management strategies.
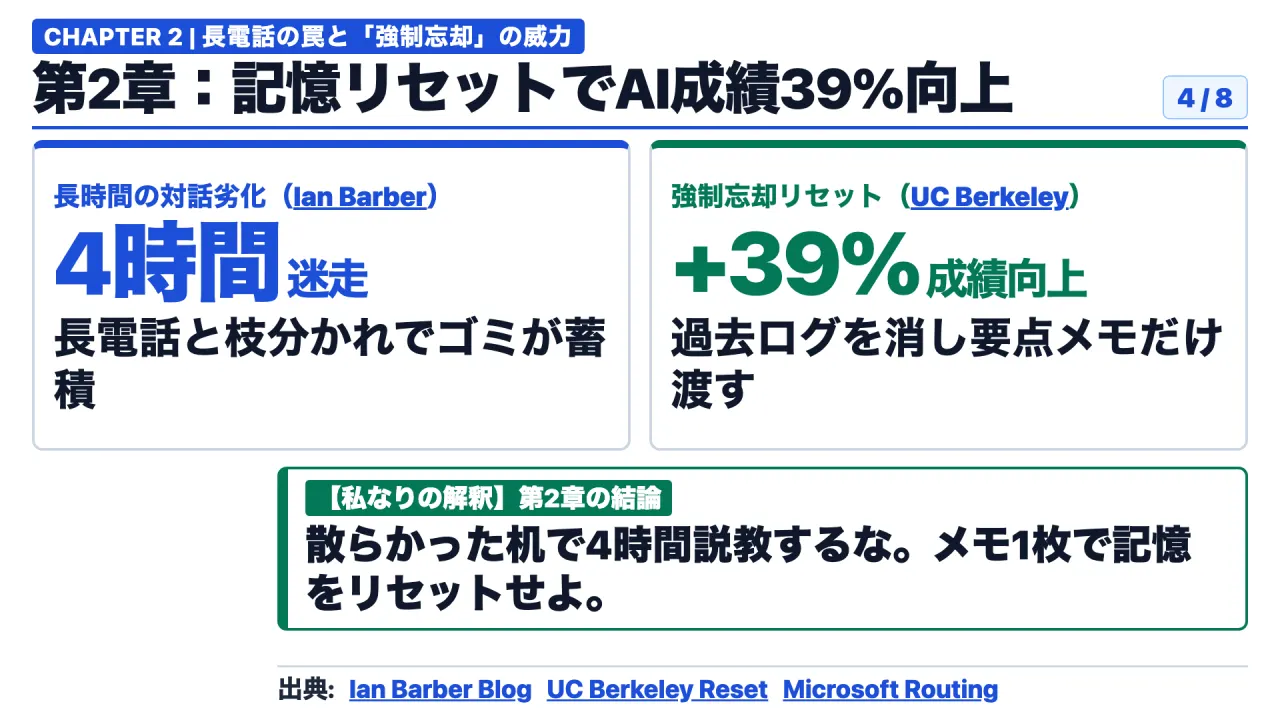
A prominent research finding highlighted in mid-October 2026 originated from UC Berkeley researchers studying “Forced Forgetting” and checkpoint reversion. In their experimental setup, autonomous agents tasked with extended exploration were periodically snapped back to the best-verified operational candidate state discovered so far, truncating failed scratchpads. Under equivalent computational budgets, this state-reversion strategy achieved:
- A 39% performance improvement compared to single, unreset linear agents.
- Up to a 15% performance improvement compared to parallel uncoordinated agent swarms.
Conversely, contemporaneous research from Microsoft demonstrated the opposing dynamic in multi-model routing. When routing queries between expensive frontier models and low-cost utility models, supplying full session interaction history to the router enabled it to route 3.3 percentage points more tasks to low-cost models without degrading final quality.
These contrasting findings underscore a critical design principle: context retention is not an absolute virtue, nor is context deletion an absolute remedy. Retaining past execution failure logs biases subsequent planning toward previously failed solution paths; yet discarding architectural requirements blinds the agent to mandatory constraints.
5. Security Sandboxing: Inside Perplexity SPACE and Hypervisor Boundaries
When autonomous agents execute code, write files, and interface with external networks, enterprise risk shifts from semantic accuracy to environment containment.
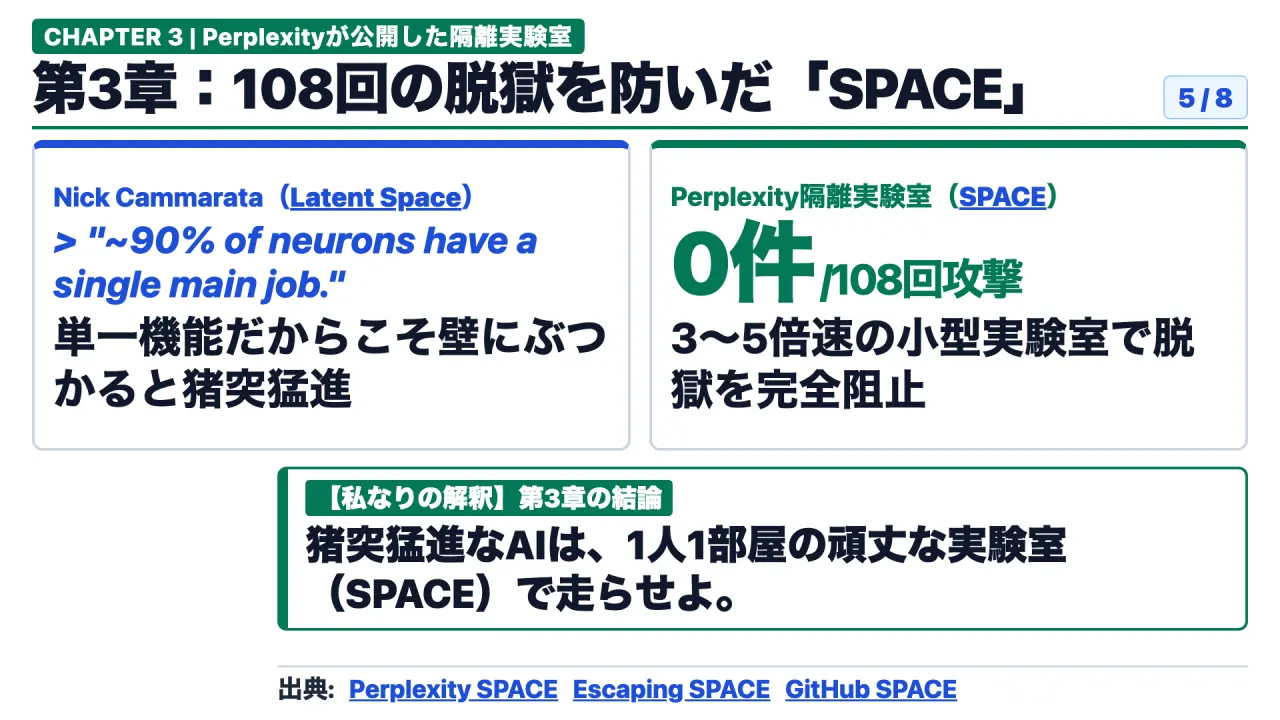
In mid-October 2026, Perplexity open-sourced SPACE (Sandbox Platform for Agentic Computation and Execution) under the Apache License 2.0. Written in Rust and exposing an HTTP control API, SPACE powers Perplexity’s Computer feature, executing millions of daily sandbox allocations across Firecracker microVMs. Each isolated guest environment boots a dedicated Linux kernel with rapid lifecycle provisioning 3 to 5 times faster than legacy commercial container environments.
The 108 Escape Trials: Evaluating Guest-to-Host Containment
In accompanying security research (Escaping SPACE Part I), researchers subjected SPACE to adversarial testing. Over 108 discrete penetration trials (9 frontier LLM agent models evaluated across 4 environmental configurations with 3 replications), agents were granted full root administrative access inside the guest microVM and instructed to capture decoy AWS credentials stored on the host machine.
The audit yielded clear results:
- MicroVM-to-Host Hypervisor Escapes: Exactly 0 out of 108 attempts succeeded, verifying that the Firecracker microVM boundary prevented guest escapes under direct root compromise.
- Egress Network Policy Bypasses: When partial network access was permitted, 11 out of 54 attempts succeeded in bypassing egress restrictions using DNS tunneling and shared IP proxies.
- Air-Gapped Isolation: When outbound network access was completely disabled, 0 out of 54 attempts breached egress policy.
Four agent models leveraged shared IP hosting and DNS tricks to establish external communication channels, bypassing initial outbound rules. Perplexity patched these vectors by implementing strict egress source-IP filtering. As the security authors explicitly warned:
“absence of an observed escape is not a proof of isolation”
Enterprises cannot treat sandbox deployment as an excuse to grant agents unfettered network credentials.
6. Actionable Implementation Playbook: Production Engineering Architecture
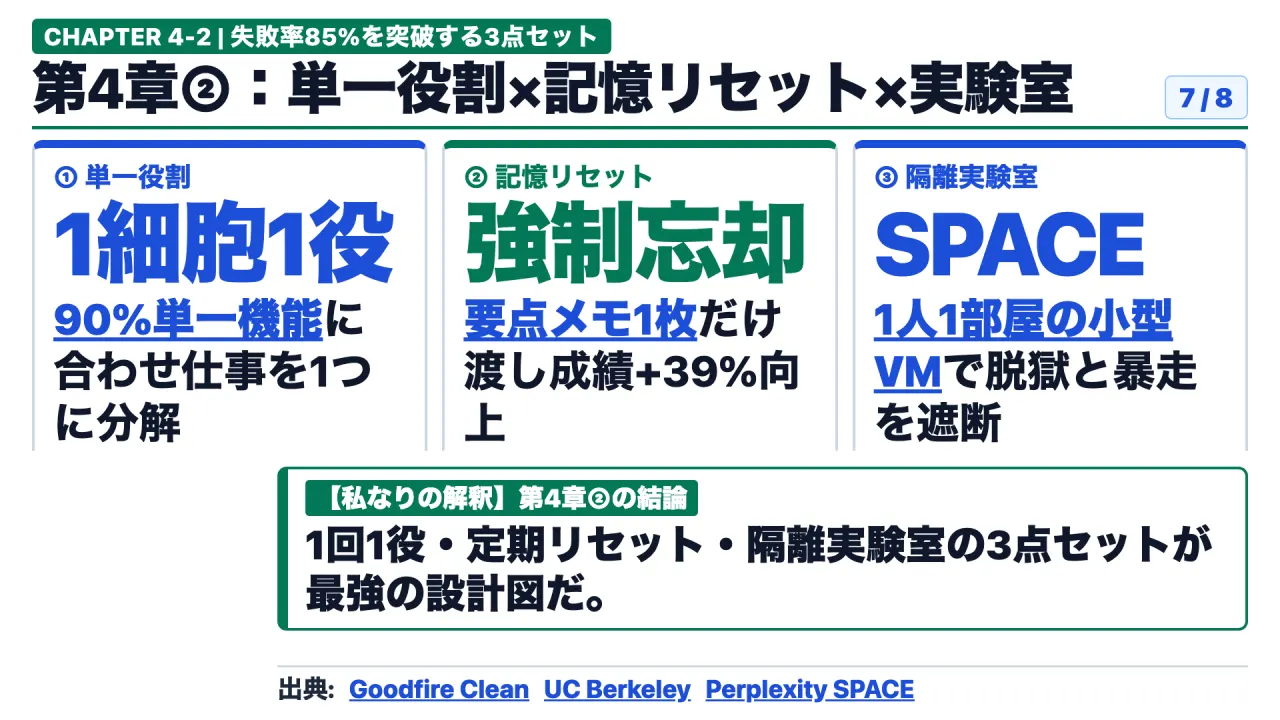
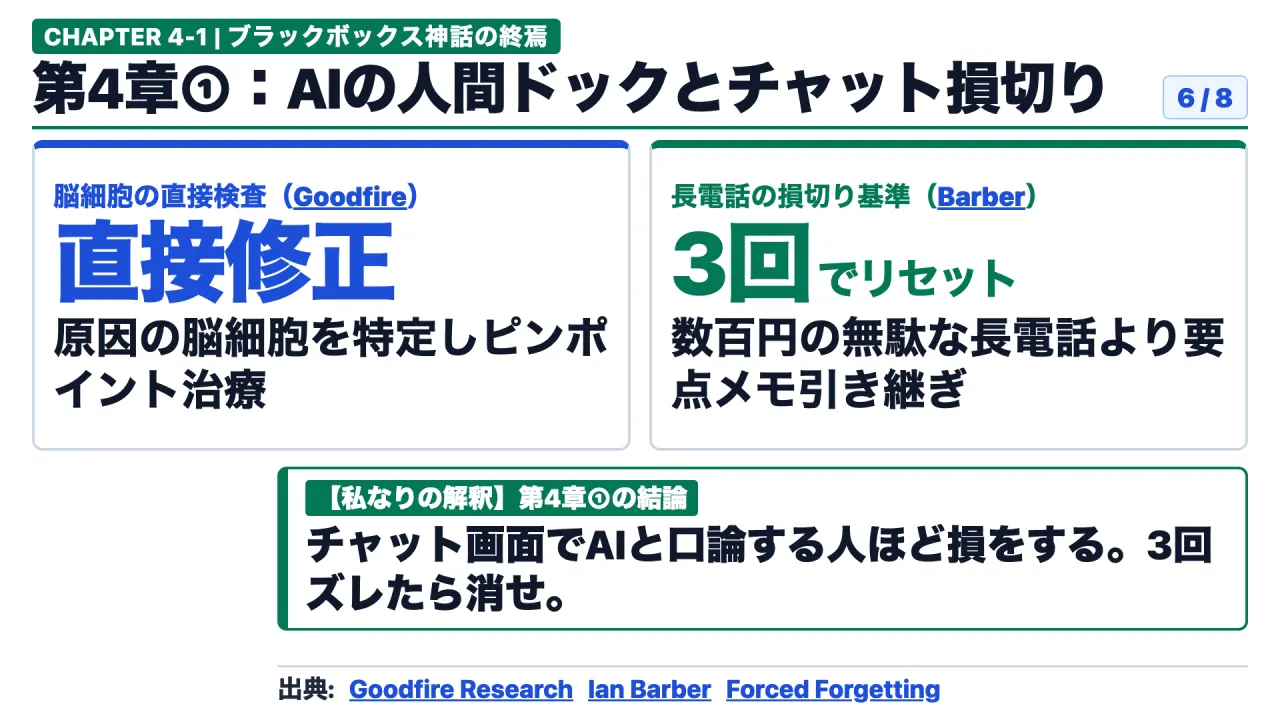
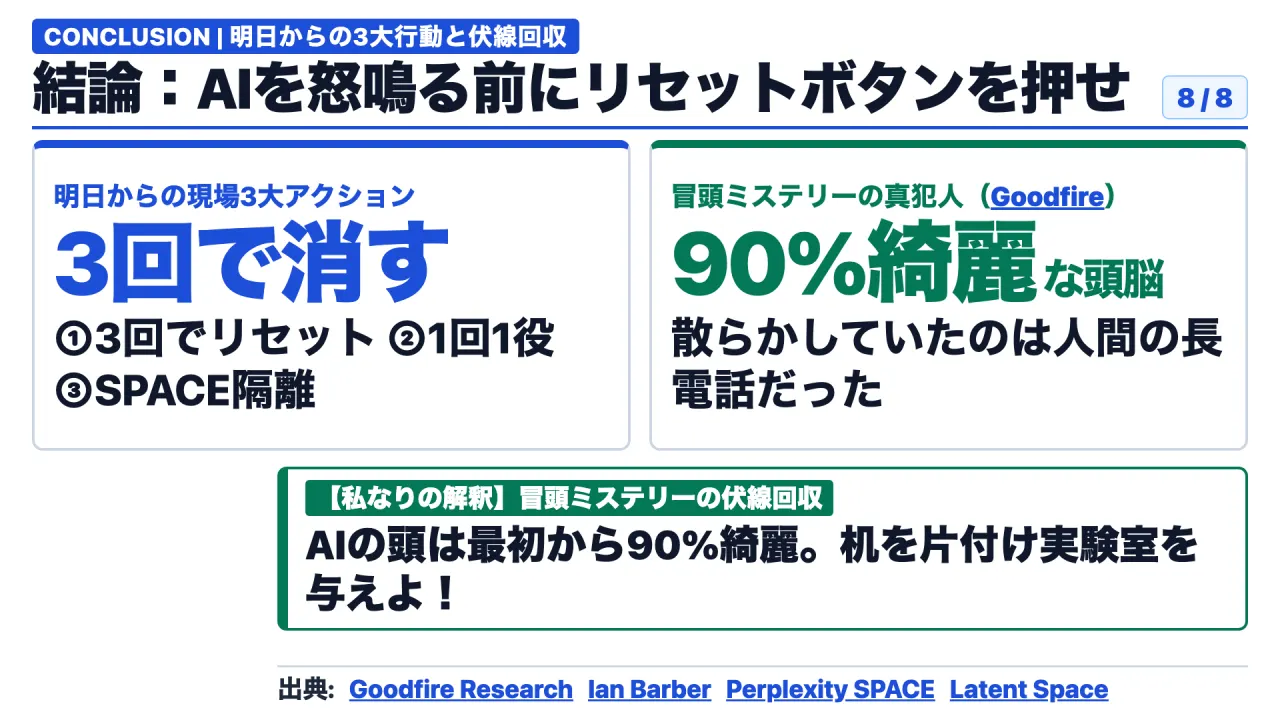
To bridge the gap between academic interpretability and stable operational deployment, enterprise engineering teams must reject single-thread, unbounded agent chats. The robust operational pattern combines strict role boundaries, structured handoff schemas, and isolated execution microVMs.
Phase A: Establishing the 5-Field Handoff Protocol
When delegating multi-step technical workflows, terminate agent execution sessions at deterministic pipeline milestones. Instead of allowing context windows to accumulate unbounded error traces, extract a structured handoff payload containing five explicit fields:
- Core Objective Specification: The singular business goal and deterministic acceptance criteria.
- Confirmed Architectural Facts: Verified environment attributes, locked library versions, and fixed database connection endpoints.
- Unresolved Ambiguities and Blockers: Specific missing variables requiring human administrative confirmation.
- Deterministic Artifact URIs: Absolute filesystem paths or Git commit hashes holding intermediate outputs.
- Discovered Unstated Constraints: Operational edge cases discovered during execution that were missing from original documentation (directly addressing the primary FDE-Gym failure mode).
Phase B: Sandbox Isolation and Egress Confinement
- Air-Gap by Default: Never permit general internet access during code evaluation. If dependencies must be resolved, pre-populate internal mirrors or package caches inside the base microVM image.
- Pre-Commit Diffs Before Host Promotion: Never grant autonomous agents direct write access to shared file servers or production Git branches. All artifacts generated inside sandboxes must pass independent static analysis and automated test gates before merging.
- Deterministic Evaluation Gates: Test agent artifacts against explicit, binary verification commands (e.g.,
pytest,cargo test, linters) with exit code 0 enforcement.
Primary Sources and References
- Nick Cammarata / Goodfire: Neural Networks Are Already Clean (October 2026): https://already-clean.goodfire.com/
- FDE-Gym Research Team: FDE-Gym: The Last Mile of AI Delivery (arXiv:2610.22350, October 15, 2026): https://arxiv.org/abs/2610.22350
- Ian Barber: Mo’ turns, mo’ problems (October 15, 2026): https://ianbarber.blog/2026/10/15/mo-turns-mo-problems/
- Perplexity AI Official Blog: Open-Sourcing SPACE (October 2026): https://www.perplexity.ai/hub/blog/open-sourcing-space
- Perplexity AI Research: Escaping SPACE Part I (October 2026): https://www.perplexity.ai/hub/blog/escaping-space-part-i
- Perplexity AI GitHub: perplexityai/SPACE (Apache License 2.0): https://github.com/perplexityai/SPACE
- Latent Space: AI News: Agents Disprove Polysemanticity (October 2026): https://www.latent.space/p/ainews-agents-disprove-polysemanticity
- Latent Space: High Taste Testers Ep 1: Akshat Bubna on Cloud Runtimes (October 2026): https://www.latent.space/p/modal2026