The RLVR Ceiling and Autonomous Horizons: Why Reasoning Models Lose to Base LLMs at 100 Attempts
Tsinghua researchers expose that reinforcement learning with verifiable rewards sharpens single-turn accuracy while destroying exploration diversity—colliding with METR’s 50-minute autonomous ceiling and the Karpathy-Amodei debate.
Published: October 24, 2026 | Read time: ~10 min | Watch Video (Japanese)
1. Executive Summary: The Inconvenient Truth Behind the Reasoning Model Boom
Over the past eighteen months, the frontier artificial intelligence industry experienced a monumental paradigm shift: the pivot from brute-force pre-training scaling laws toward post-training Reinforcement Learning with Verifiable Rewards (RLVR). Pioneered by models such as OpenAI o1 and DeepSeek-R1, laboratories worldwide demonstrated astonishing benchmark gains across competitive mathematics and programming. Popular narrative quickly concluded that self-directed reinforcement learning allows models to invent novel problem-solving patterns, achieving unbounded superhuman intelligence.
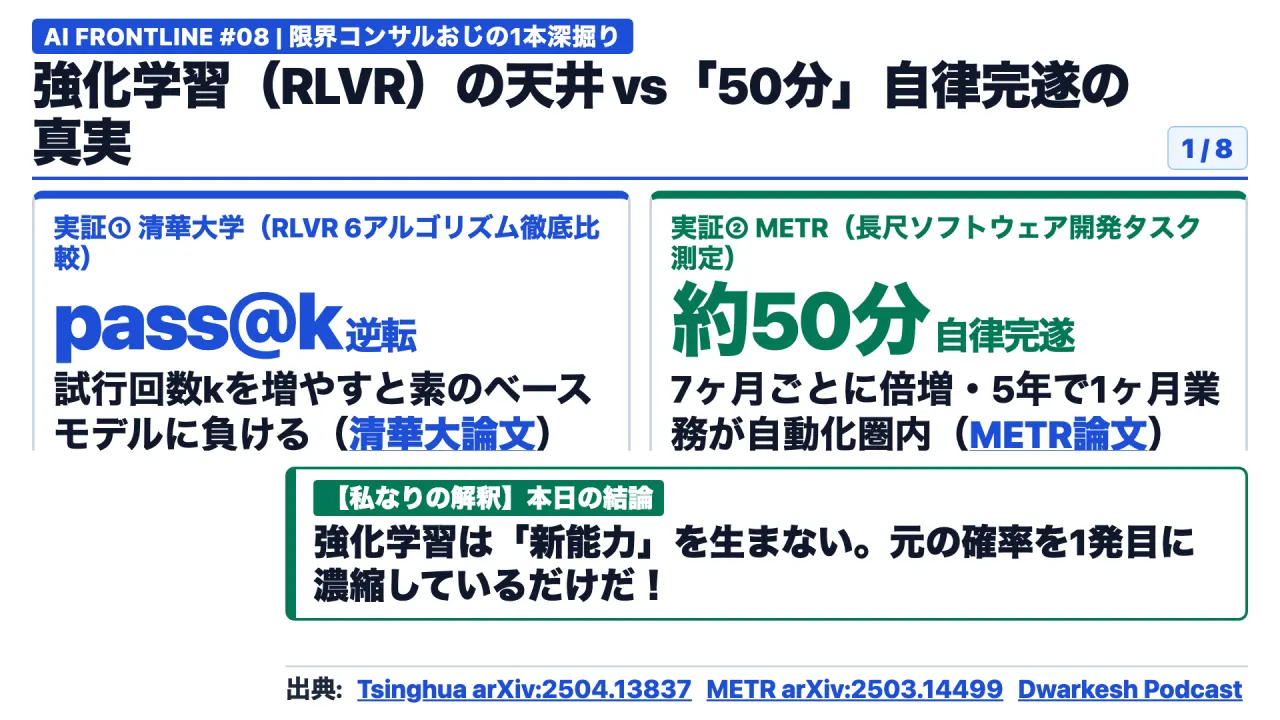
However, groundbreaking empirical research published by a Tsinghua University research team led by Yang Yue shattered this foundational assumption. When evaluating frontier models across complex mathematical and algorithmic challenges, researchers discovered a startling counter-intuitive phenomenon: while RLVR substantially increases single-turn accuracy (pass@1), increasing the sampling budget (pass@k for $k \ge 100$) reveals that the un-tuned base model systematically outperforms the reinforcement-learned model. Across six mainstream RL algorithms, RLVR failed to expand the fundamental reasoning frontier beyond the pre-trained base model’s intrinsic capacity.
Simultaneously, empirical evaluations conducted by model evaluation organization METR (Measuring Effective Thinking in Runtimes, authored by Thomas Kwa et al.) established that the 50% autonomous completion duration for state-of-the-art models on real-world software engineering stands at approximately 50 minutes. While this autonomous operational horizon has doubled every seven months since 2019, attempting to delegate software tasks extending beyond 50 minutes results in catastrophic drift.
These empirical realities sit at the epicenter of a profound ten-year architectural dispute between Andrej Karpathy (warning that sparse reinforcement learning amounts to “sipping supervision through a straw” and predicting true autonomy requires a decade) and Dario Amodei (betting that massive compute scaling will birth a “country of geniuses in a datacenter” within years).
2. Theoretical Foundations: Deconstructing RLVR and the pass@k Metric
To diagnose the mechanics governing this ceiling, we must formalize two core operational primitives.
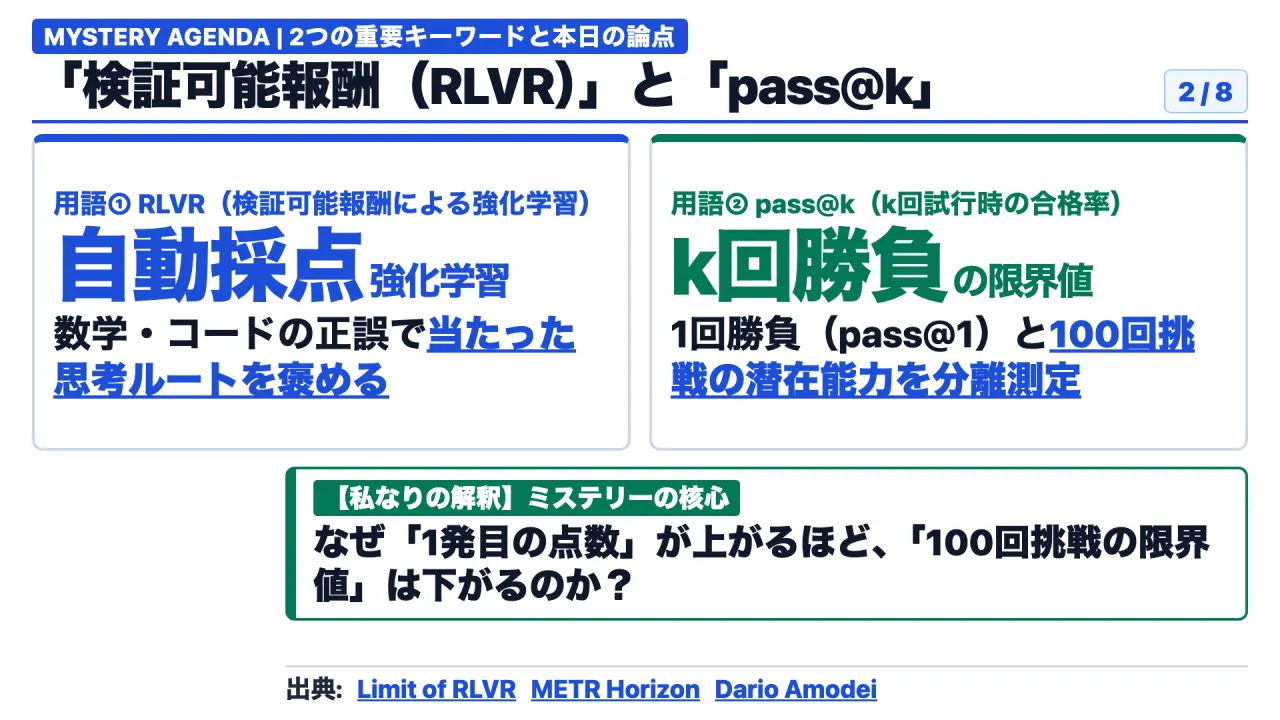
Reinforcement Learning with Verifiable Rewards (RLVR)
Unlike Reinforcement Learning from Human Feedback (RLHF), which relies on subjective human preference scores, RLVR operates exclusively in domains where objective, automated ground-truth verifiers exist. In mathematics, a symbolic solver evaluates whether the final equation matches ground truth; in software engineering, a test runner executes unit tests, returning a binary compiler signal (pass or fail). When an intermediate reasoning trace generates a passing test, the optimizer increases the probability weights of the tokens in that trajectory.
The pass@k Sampling Evaluation Metric
To measure how models behave under variable compute budgets, researchers deploy the pass@k metric. An evaluation harness prompts the model to generate $k$ independent solution candidates for a single challenging problem. If at least one of the $k$ candidates passes the unit test suite or ground-truth verifier, the trial is graded as a success:
pass@1(Single-Shot Accuracy): The standard benchmark setting where the model receives exactly one attempt.pass@100topass@256(Exploration Boundary): The model generates 100 to 256 diverse solution paths. This metric measures the full breadth of the model’s latent problem-solving knowledge.
3. The Tsinghua Finding: Distribution Sharpening vs Solution Discovery
The prevailing commercial claim held that RLVR acts as an automated researcher, discovering novel cognitive pathways inaccessible to base language models. The Tsinghua University paper (“Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model?”) disproved this thesis through rigorous ablation across six representative RL algorithms.
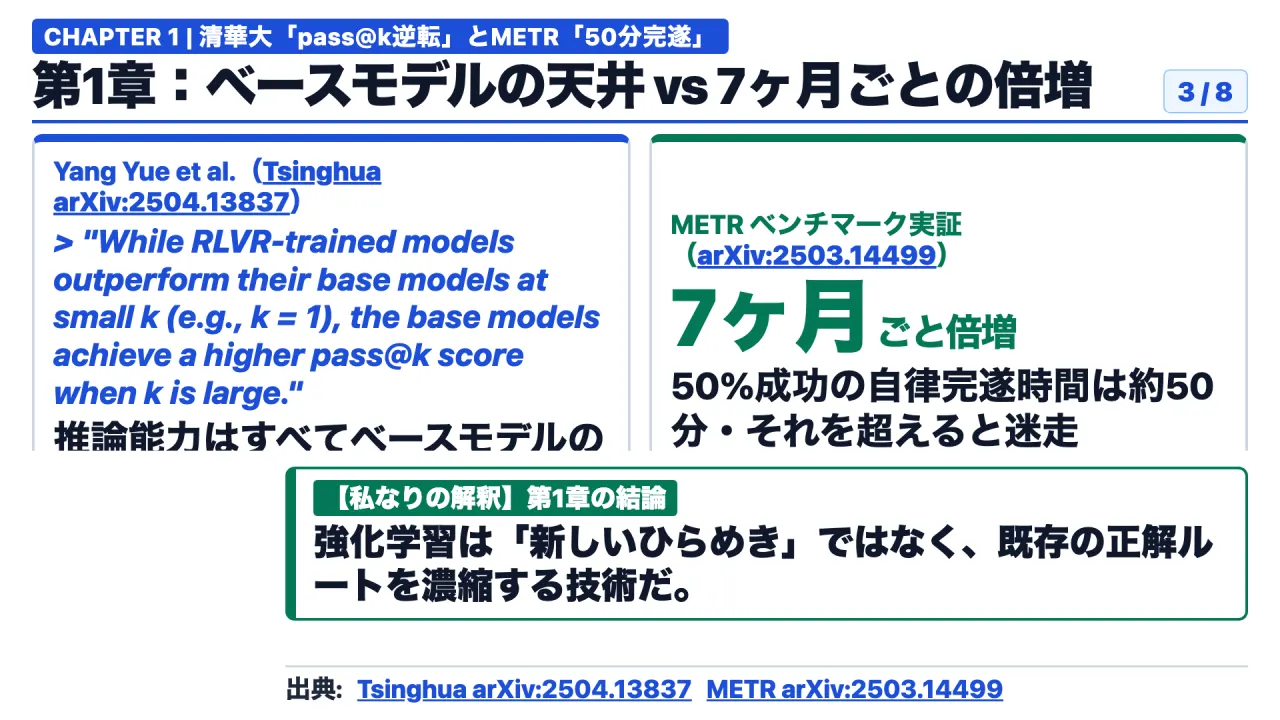
The paper’s core empirical findings establish three undeniable realities:
- The pass@k Inversion (The Reversal Phenomenon): At low sampling values ($k=1$), RLVR models decisively defeat their base model counterparts, demonstrating massive improvements on standard benchmarks. However, as sampling increases toward $k=64$, $k=100$, and $k=256$, the curves intersect: the un-tuned base model consistently overtakes the RLVR model, ultimately achieving a substantially higher ceiling of solved problems.
- Coverage and Latent Space Boundedness: Mathematical coverage analysis demonstrated that every single problem-solving pattern exhibited by the RLVR model was already present in the latent space of the un-tuned base model. RLVR did not generate a single genuinely novel reasoning primitive.
- Distribution Sharpening (The Diversity Tax): Why does the base model win at high $k$? Consider an un-fine-tuned base model as an eccentric polymath who memorized millions of textbooks. When asked to solve 100 problems, it makes sloppy arithmetic blunders on 95 of them, but on the remaining 5 attempts, it explores wild, unconventional approaches that crack the hardest edge cases.
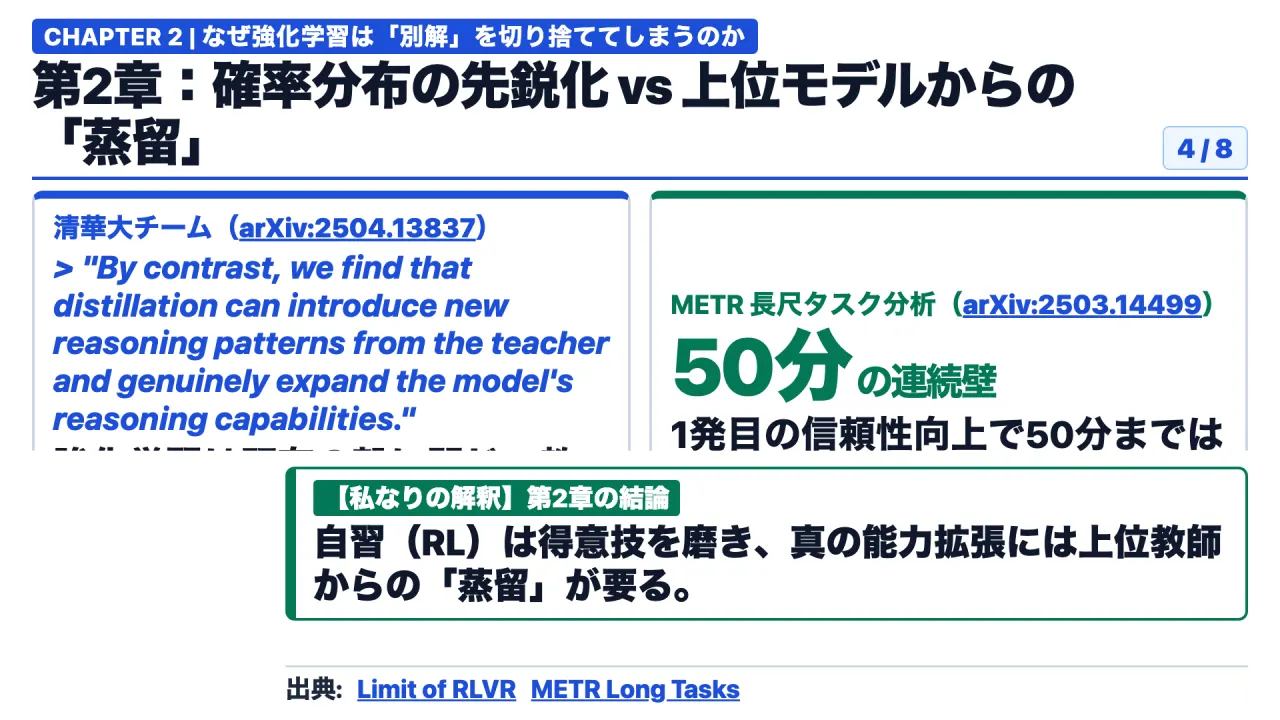
When RLVR is applied, the optimizer penalizes the 95 failed attempts and aggressively reinforces the single most common path that produced a correct answer. The probability distribution sharpens around one safe, standard methodology. While this skyrockets the odds of getting a routine problem right on the first attempt (pass@1), it completely purges the exploratory diversity required to solve complex edge cases. When confronted with an atypical problem where standard methodologies fail, the RLVR model repeats the same flawed conventional approach 100 times, failing on every attempt.
The Lone Exception: Model Distillation
Crucially, the Tsinghua study identified exactly one mechanism that genuinely expanded the reasoning frontier: model distillation from a larger, superior teacher model. When a compact model was fine-tuned on the structured reasoning traces generated by a substantially larger frontier system, its pass@k ceiling expanded upward across all values of $k$. Internal self-play RLVR failed to break through intrinsic cognitive walls; absorbing external cognitive traces from superior models succeeded.
4. The METR 50-Minute Ceiling: Scaling Autonomous Software Engineering
While Tsinghua investigated mathematical sampling diversity, research published by METR (Thomas Kwa et al., “Measuring AI Ability to Complete Long Software Tasks”) quantified operational endurance in real-world software engineering environments.
| Metric Parameter | Historical / Measured Value | Architectural Significance |
|---|---|---|
| 50% Autonomous Horizon (Current) | ~50 Minutes of human-equivalent effort | The duration beyond which model success collapses below 50% |
| Historical Doubling Velocity | Every ~7 Months (tracked since 2019) | Exponential expansion of uninterrupted agent execution |
| 5-Year Extrapolation | ~1 Month of continuous engineering work | Projected enterprise capacity if exponential scaling holds |
| Current Task Horizon Failure Mode | Terminal drift, broken tool loops, context bloat | Lack of internal process-level self-correction |
METR evaluated frontier models on real-world software development tasks harvested from open-source repositories—tasks that required human software engineers between 15 minutes and several hours to resolve.
The benchmark measured the 50% autonomous completion time: the maximum duration of a human software task that an AI model can execute completely autonomously with at least a 50% probability of success.
The good news: this metric has doubled every seven months since 2019, climbing from fractions of a minute to approximately 50 minutes. The sobering reality: the curve is unforgiving. On tasks requiring 30 minutes of human effort, state-of-the-art models succeed reliably. However, once a task demands more than 50 minutes of continuous reasoning, the probability of successful completion plunges toward zero. Without continuous human intervention or external testing gates, autonomous agents inevitably wander down hallucinatory architectural dead-ends.
5. The Great Frontier Debate: Karpathy’s Straw vs Amodei’s Compute Blob
The empirical findings of Tsinghua and METR illuminate the philosophical and technical divide between two legendary AI pioneers, voiced during in-depth interviews on the Dwarkesh Podcast.
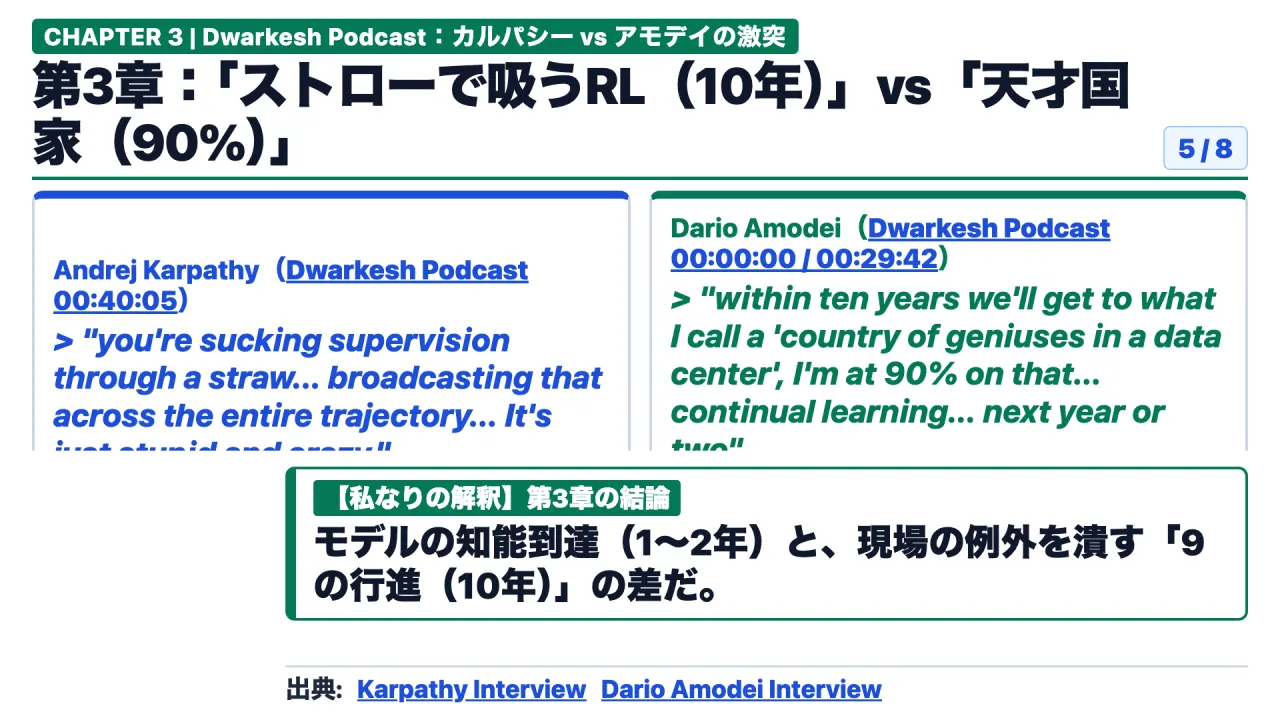
Andrej Karpathy: “Sipping Supervision Through a Straw”
In his appearance (Chapter: “RL is terrible”, 00:40:05), former Tesla AI Director and OpenAI co-founder Andrej Karpathy offered an unsparing critique of contemporary reinforcement learning:
“Today’s reinforcement learning is like sipping supervision through a tiny straw. A model generates hundreds of intermediate reasoning tokens over a minute of compute, and at the very end receives a single 1-bit binary reward: success or failure. The optimizer takes that crude 1-bit signal and indiscriminately reinforces or penalizes every single token in the trajectory.”
Karpathy highlighted the profound noise injected by binary outcome rewards: if a model stumbled across the correct answer by sheer coincidence despite harboring three hallucinated logical leaps along the way, RLVR rewards and entrenches those hallucinations. Drawing analogies to autonomous driving, Karpathy asserted that executing the “March of the 9s”—advancing reliability from 95% to 99%, 99.9%, and 99.99% in complex environments—requires three to four fundamental algorithmic breakthroughs. Karpathy concluded that truly reliable autonomous agents remain at least a decade away.
Dario Amodei: The Country of Geniuses in a Datacenter
Appearing in a subsequent episode (00:00:00, 00:29:42), Anthropic CEO Dario Amodei championed the opposing thesis, reiterating his 2017 “Huge Blob of Compute” hypothesis:
“People consistently underestimate how close we are to the exponential destination. I place a 90% probability that within ten years—and potentially much sooner—we will achieve what I call a ‘country of geniuses in a datacenter’. Furthermore, the problem of continual learning, where models learn organically during deployment, is likely to be solved within the next one to two years.”
Amodei argued that historical scaling skepticism has repeatedly dissolved when confronted with massive compute scaling. In his view, expanding long-context retrieval, scaling inference-time reasoning compute, and coupling agents to execution environments will naturally compress the timeline to transformative economic utility.
6. Structural Synthesis: Reconciling Karpathy and Amodei
Are Karpathy and Amodei fundamentally contradictory, or are they describing different horizons of the same curve?
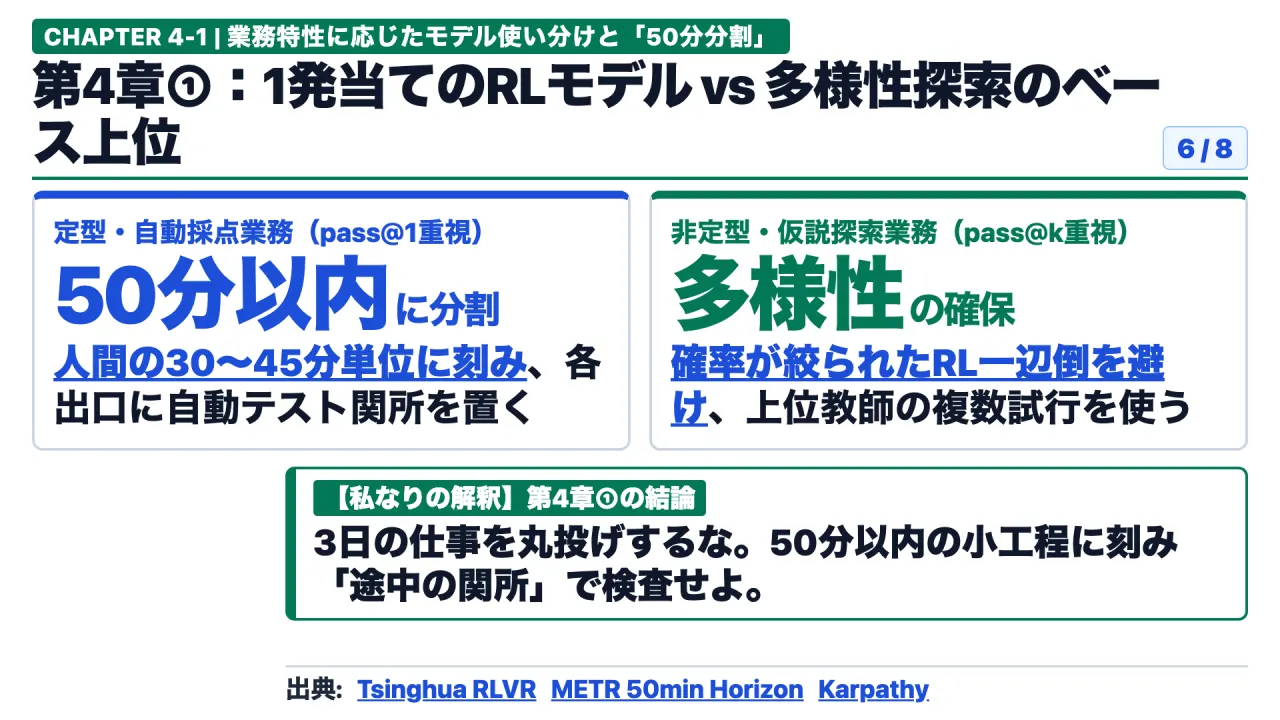
Synthesizing their arguments alongside Tsinghua and METR data reveals the unifying truth:
- Amodei is right about Model Intelligence: The raw mathematical, coding, and benchmark reasoning scores of models will saturate expert human levels across datacenters within one to three years.
- Karpathy is right about Operational Integration: Bridging that raw intelligence into enterprise banks, chemical factories, and mission-critical production codebases—navigating messy enterprise exceptions, dirty data, ambiguous permissions, and zero-error tolerance—is an arduous ten-year journey of systems engineering.
7. Enterprise Engineering Blueprint: The Three-Tier Hybrid Architecture
Enterprise software architects cannot wait a decade for artificial general intelligence, nor can they blindly trust current models on multi-hour tasks. Production success demands designing systems around current empirical constraints.
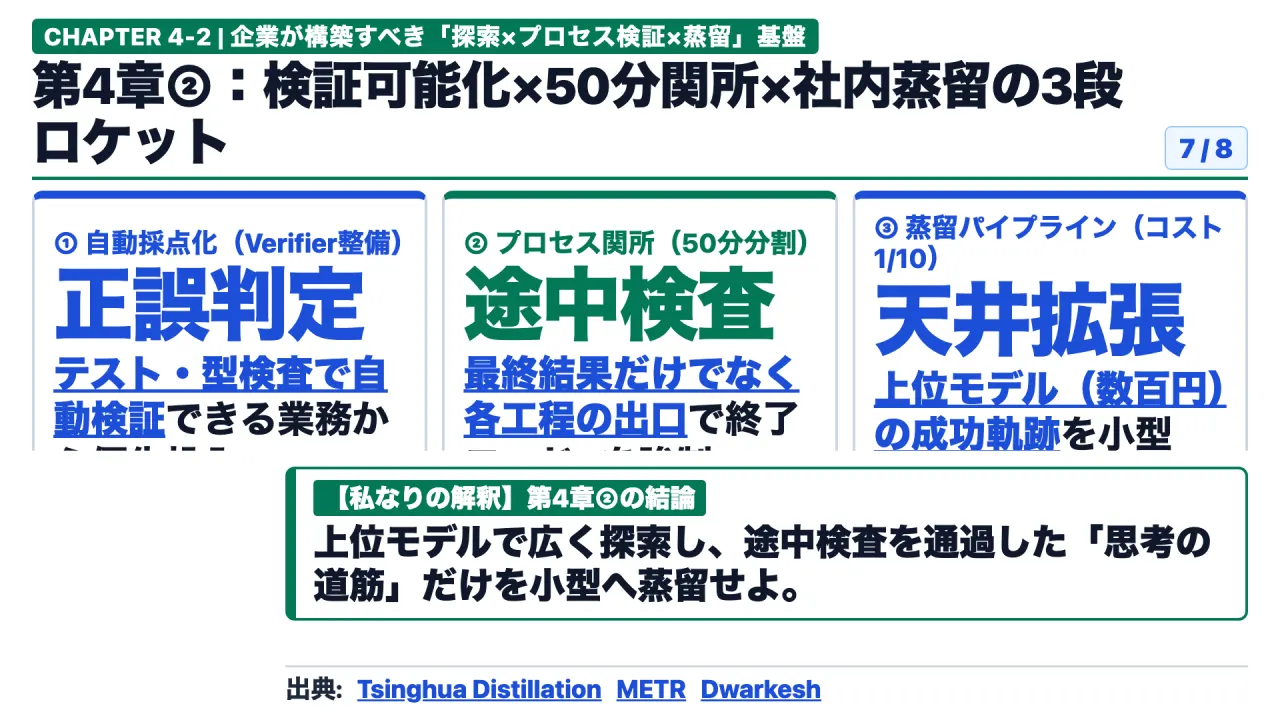
Tier 1: Task Domain Segregation (Verifiable vs Exploratory)
- Deterministic Workflows (Deploy RLVR & Distilled Models): In tasks with clear ground-truth verifiers (routine code refactoring, SQL query formatting, API schema mapping, invoice matching), single-shot accuracy is paramount. Deploy RL-tuned or distilled compact models ($0.10 to $0.50 per 1M tokens) to execute high-volume operations with minimal latency.
- Exploratory Architecture (Deploy Diverse Base / Frontier Models): For architectural system design, novel vulnerability research, or debugging elusive distributed systems bugs, RLVR models suffer from distribution sharpening. Deploy raw frontier models with higher sampling temperatures or parallel diverse seed generation (
pass@ksampling) to capture non-conventional problem-solving paths.
Tier 2: The 50-Minute Task Horizon Boundary
Never hand an autonomous agent an unbounded objective (e.g., “Refactor our entire payment microservice architecture”). In accordance with METR’s findings, decompose complex business workflows into discrete execution units that a human engineer would complete within 30 to 45 minutes.
At each boundary, place an automated, deterministic verification gate (unit tests, static linters, typecheckers, integration smoke tests). The agent is strictly prohibited from advancing to stage $N+1$ until stage $N$ achieves exit code 0.
Tier 3: Asymmetric Distillation Pipelines
Rather than executing every production turn through massive frontier reasoning models costing dollars per query, establish an internal distillation loop:
- Allow high-capacity frontier reasoning models to explore challenging architectural edge cases using high sampling budgets.
- Filter the resulting trajectories through automated deterministic unit test suites, discarding faulty runs and capturing verified end-to-end reasoning traces.
- Distill these verified reasoning chains into compact, specialized internal models. This permanently elevates the
pass@kceiling of internal infrastructure while slashing enterprise inference costs by up to 90%.
8. Actionable Takeaways for Enterprise Engineering Teams
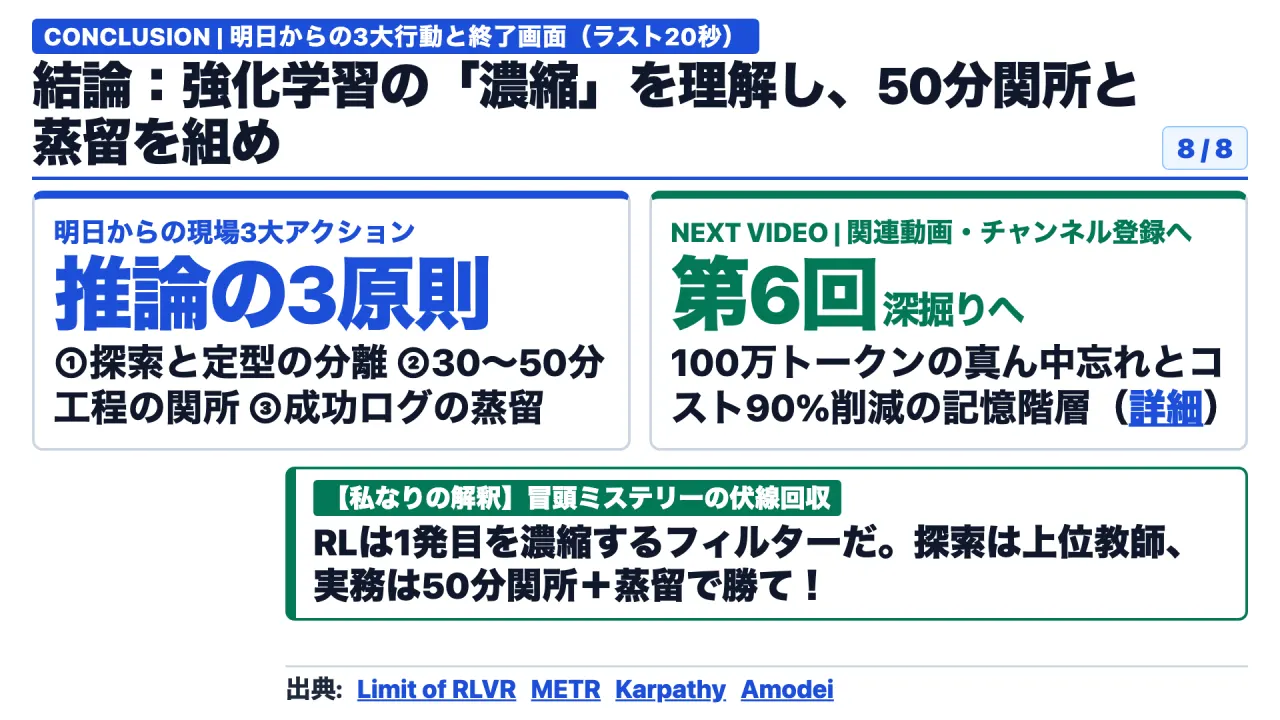
Engineering leaders and technical staff should implement three operational principles immediately:
- Beware the Sampling Illusion: High benchmark scores on single attempts (
pass@1) do not equate to superior problem-solving depth. If an engineering initiative requires exploring novel architectures or debugging rare defects, evaluate candidate models across diverse multi-sample generation (pass@100) rather than standard leaderboards. - Hardcode Checkpoints Every 30 Minutes of Effort: Restructure agentic automation pipelines so that no model operates without automated code compilation or test execution for more than 30 equivalent minutes of work. Deterministic checkpoints eliminate hallucinatory drift.
- Inspect the Intermediate Straw: To avoid Karpathy’s “straw” trap, evaluate agents on the fidelity of their intermediate tool interactions and reasoning logs, rather than merely checking whether the final output looked convincing.
By recognizing the mathematical boundaries of reinforcement learning and structuring agent runtimes around deterministic verification gates, engineering organizations can convert fragile probabilistic models into robust, enterprise-grade autonomous systems.
Primary Sources and References
- Tsinghua University Research (Yang Yue et al.): Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model? — arXiv:2504.13837
- METR Research (Thomas Kwa et al.): Measuring AI Ability to Complete Long Software Tasks — arXiv:2503.14499
- Dwarkesh Podcast: Andrej Karpathy — AGI is Still a Decade Away and the Limits of Reinforcement Learning — Dwarkesh Podcast Episode
- Dwarkesh Podcast: Dario Amodei — We Are Near the End of the Exponential and the Datacenter Genius Model — Dwarkesh Podcast Episode
- Consuloji Deep Dive Video (Japanese): 「なぜ『強化学習』で鍛えたはずの推論AIが、100回試行すると元のモデルに負けるのか」 — Watch on YouTube